Model benchmarks with latency and calibrationbenchmarks-calibration-table
Use in Plus UI
npx shadcn@latest add https://blocks.plusui.com/r/benchmarks-calibration-table.jsonStats · 13 variants
← → to step through · + on a thumbnail to compare side by side (up to 3)
‹
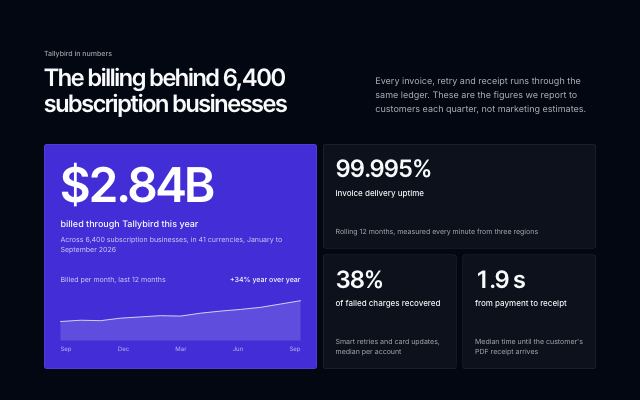 Inverted bento with a hero metric+
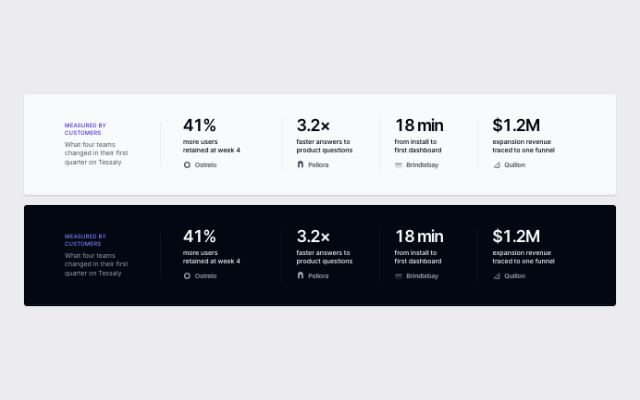 Inline proof band under a hero+
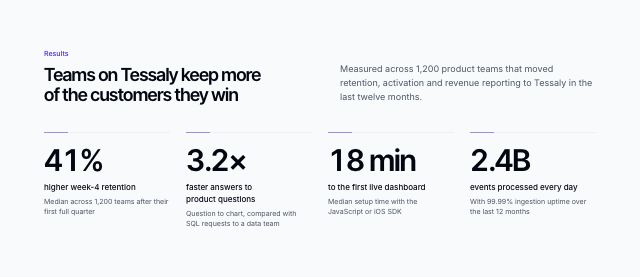 Metric band with sourced numbers+
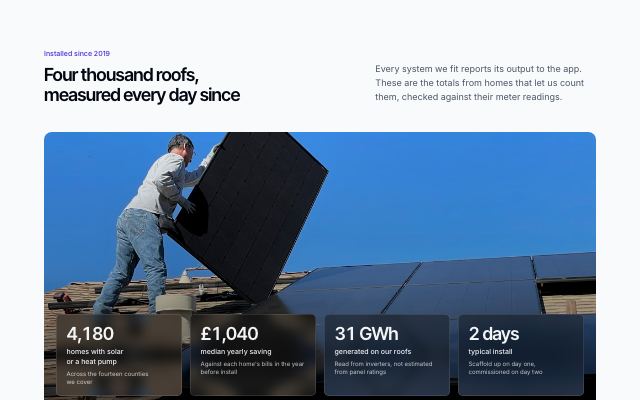 Figures over a full-bleed photo+
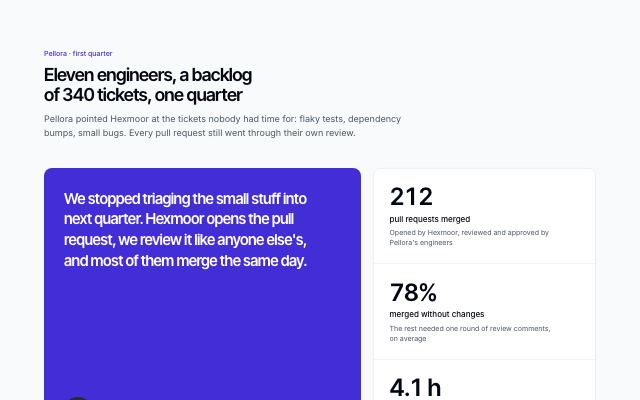 Metrics beside a customer quote+
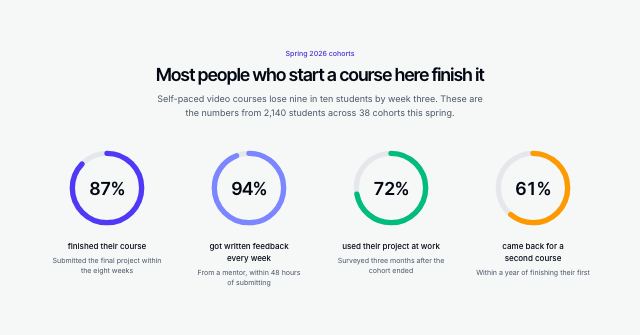 Metrics as progress rings+
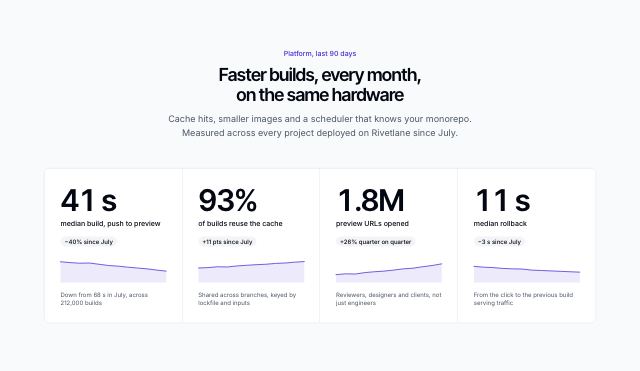 Big numbers with sparklines+
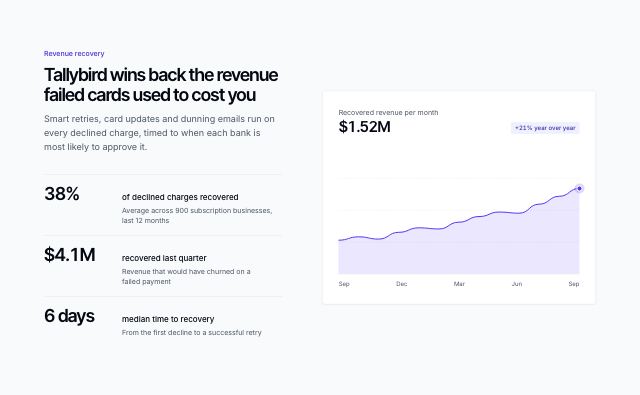 Metrics beside a trend chart+
 Growth milestones on a timeline+
 Impact figures with a map of project sites+
 Where the money goes+
 Model benchmarks with latency and calibration
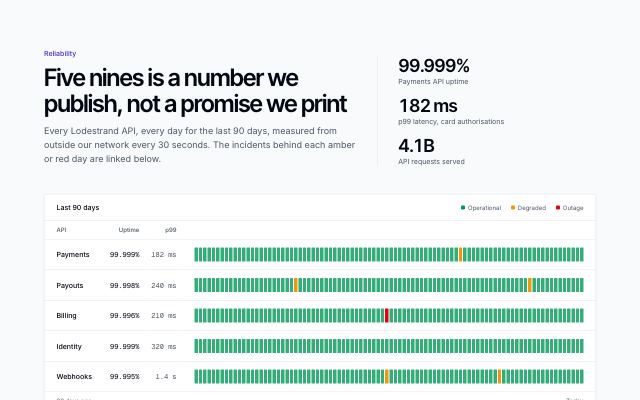 Reliability ledger with daily uptime bars+
/preview/benchmarks-calibration-table
Open ↗Default content
{
  "eyebrow": "Benchmarks",
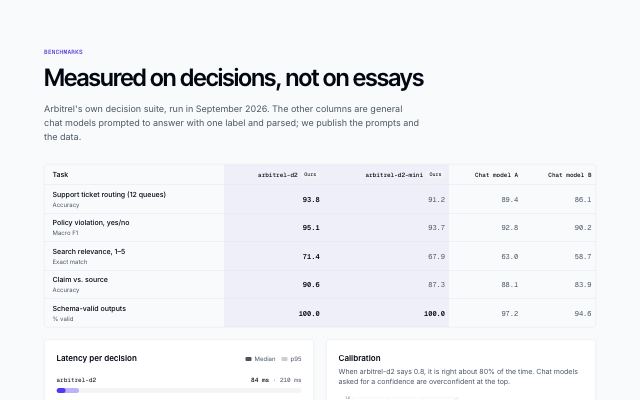
  "title": "Measured on decisions, not on essays",
  "description": "Arbitrel's own decision suite, run in September 2026. The other columns are general chat models prompted to answer with one label and parsed; we publish the prompts and the data.",
  "models": [
    {
      "name": "arbitrel-d2",
      "ours": true
    },
    {
      "name": "arbitrel-d2-mini",
      "ours": true
    },
    {
      "name": "Chat model A",
      "ours": false
    },
    {
      "name": "Chat model B",
      "ours": false
    }
  ],
  "tasks": [
    {
      "name": "Support ticket routing (12 queues)",
      "metric": "Accuracy",
      "scores": [
        93.8,
        91.2,
        89.4,
        86.1
      ]
    },
    {
      "name": "Policy violation, yes/no",
      "metric": "Macro F1",
      "scores": [
        95.1,
        93.7,
        92.8,
        90.2
      ]
    },
    {
      "name": "Search relevance, 1–5",
      "metric": "Exact match",
      "scores": [
        71.4,
        67.9,
        63,
        58.7
      ]
    },
    {
      "name": "Claim vs. source",
      "metric": "Accuracy",
      "scores": [
        90.6,
        87.3,
        88.1,
        83.9
      ]
    },
    {
      "name": "Schema-valid outputs",
      "metric": "% valid",
      "scores": [
        100,
        100,
        97.2,
        94.6
      ]
    }
  ],
  "latency": {
    "title": "Latency per decision",
    "p50": [
      84,
      52,
      610,
      940
    ],
    "p95": [
      210,
      130,
      1480,
      2300
    ]
  },
  "calibration": {
    "title": "Calibration",
    "description": "When arbitrel-d2 says 0.8, it is right about 80% of the time. Chat models asked for a confidence are overconfident at the top.",
    "bins": [
      0.55,
      0.65,
      0.75,
      0.85,
      0.95
    ],
    "curves": [
      [
        0.54,
        0.66,
        0.74,
        0.86,
        0.94
      ],
      [
        0.52,
        0.63,
        0.76,
        0.83,
        0.93
      ],
      [
        0.49,
        0.55,
        0.62,
        0.7,
        0.81
      ],
      [
        0.45,
        0.5,
        0.57,
        0.64,
        0.74
      ]
    ],
    "ece": [
      0.018,
      0.027,
      0.094,
      0.141
    ]
  },
  "labels": {
    "task": "Task",
    "metric": "Metric",
    "ours": "Ours",
    "p50": "Median",
    "p95": "p95",
    "ms": "ms",
    "predicted": "Stated confidence",
    "observed": "Observed accuracy",
    "perfect": "Perfect calibration",
    "ece": "ECE"
  },
  "methodology": "Arbitrel decision suite v3: 18,400 labelled items from five public datasets and two donated by customers, relabelled by three annotators. Single run, temperature 0, measured from a client in Frankfurt on 2026-09-22. Prompts and raw outputs are on GitHub.",
  "action": {
    "label": "Download the full report",
    "href": "#",
    "variant": "secondary"
  }
}