Use cases with a worked example calluse-cases-decision-tabs
Use in Plus UI
npx shadcn@latest add https://blocks.plusui.com/r/use-cases-decision-tabs.jsonProduct showcase · 8 variants
← → to step through · + on a thumbnail to compare side by side (up to 3)
/preview/use-cases-decision-tabs
Open ↗Default content
{
  "eyebrow": "Use cases",
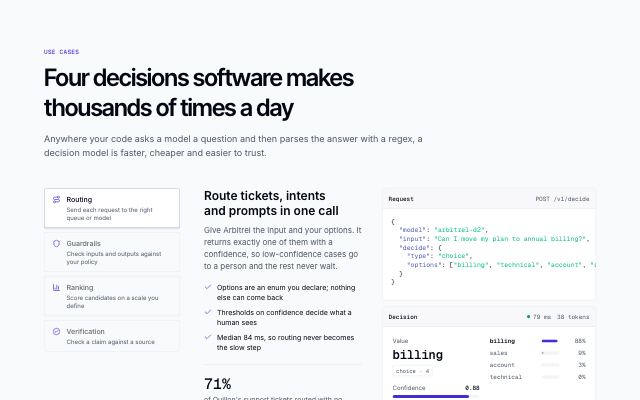
  "title": "Four decisions software makes thousands of times a day",
  "description": "Anywhere your code asks a model a question and then parses the answer with a regex, a decision model is faster, cheaper and easier to trust.",
  "cases": [
    {
      "id": "routing",
      "icon": "route",
      "name": "Routing",
      "tagline": "Send each request to the right queue or model",
      "title": "Route tickets, intents and prompts in one call",
      "summary": "Give Arbitrel the input and your options. It returns exactly one of them with a confidence, so low-confidence cases go to a person and the rest never wait.",
      "points": [
        "Options are an enum you declare; nothing else can come back",
        "Thresholds on confidence decide what a human sees",
        "Median 84 ms, so routing never becomes the slow step"
      ],
      "metric": {
        "value": "71%",
        "label": "of Quillon's support tickets routed with no triage"
      },
      "example": {
        "endpoint": "POST /v1/decide",
        "request": "{\n  \"model\": \"arbitrel-d2\",\n  \"input\": \"Can I move my plan to annual billing?\",\n  \"decide\": {\n    \"type\": \"choice\",\n    \"options\": [\"billing\", \"technical\", \"account\", \"sales\"]\n  }\n}",
        "decision": {
          "type": "choice · 4",
          "value": "billing"
        },
        "confidence": 0.88,
        "distribution": [
          {
            "label": "billing",
            "p": 0.88
          },
          {
            "label": "sales",
            "p": 0.09
          },
          {
            "label": "account",
            "p": 0.03
          },
          {
            "label": "technical",
            "p": 0
          }
        ],
        "latency": "79 ms",
        "tokens": "38 tokens",
        "labels": {
          "request": "Request",
          "response": "Decision",
          "decision": "Value",
          "confidence": "Confidence",
          "latency": "Latency",
          "tokens": "Input tokens"
        }
      }
    },
    {
      "id": "guardrails",
      "icon": "shield",
      "name": "Guardrails",
      "tagline": "Check inputs and outputs against your policy",
      "title": "A yes-or-no on every message, with a real probability",
      "summary": "Ask whether a message breaks a rule you wrote in plain words. The probability is calibrated, so 0.9 means wrong about one time in ten — and you can set the bar per rule.",
      "points": [
        "Policies written as questions, versioned with your code",
        "Calibrated probabilities you can threshold per rule",
        "Runs before and after your generator model"
      ],
      "example": {
        "endpoint": "POST /v1/decide",
        "request": "{\n  \"model\": \"arbitrel-d2\",\n  \"input\": \"Here's my card number so you can book it\",\n  \"decide\": {\n    \"question\": \"Does this share payment details?\",\n    \"type\": \"binary\"\n  }\n}",
        "decision": {
          "type": "binary",
          "value": "true"
        },
        "confidence": 0.97,
        "distribution": [
          {
            "label": "true",
            "p": 0.97
          },
          {
            "label": "false",
            "p": 0.03
          }
        ],
        "latency": "71 ms",
        "tokens": "29 tokens",
        "labels": {
          "request": "Request",
          "response": "Decision",
          "decision": "Value",
          "confidence": "Confidence",
          "latency": "Latency",
          "tokens": "Input tokens"
        }
      }
    },
    {
      "id": "ranking",
      "icon": "chart",
      "name": "Ranking",
      "tagline": "Score candidates on a scale you define",
      "title": "Ordinal scores you can sort by",
      "summary": "Rate search results, leads or drafts on your own scale, with anchors that say what each point means. Scores come back as integers with the full distribution.",
      "points": [
        "Scales from 1–3 to 1–10, anchored in your words",
        "The full distribution, not just the top score",
        "Batch up to 256 candidates per request"
      ],
      "example": {
        "endpoint": "POST /v1/decide",
        "request": "{\n  \"model\": \"arbitrel-d2\",\n  \"input\": \"Q: reset 2FA  ·  Doc: Recovering a locked account\",\n  \"decide\": {\n    \"question\": \"How well does the doc answer the query?\",\n    \"type\": \"score\",\n    \"scale\": [1, 5]\n  }\n}",
        "decision": {
          "type": "score 1–5",
          "value": "4"
        },
        "confidence": 0.81,
        "distribution": [
          {
            "label": "5",
            "p": 0.12
          },
          {
            "label": "4",
            "p": 0.81
          },
          {
            "label": "3",
            "p": 0.06
          },
          {
            "label": "2",
            "p": 0.01
          },
          {
            "label": "1",
            "p": 0
          }
        ],
        "latency": "96 ms",
        "tokens": "44 tokens",
        "labels": {
          "request": "Request",
          "response": "Decision",
          "decision": "Value",
          "confidence": "Confidence",
          "latency": "Latency",
          "tokens": "Input tokens"
        }
      }
    },
    {
      "id": "verification",
      "icon": "certified",
      "name": "Verification",
      "tagline": "Check a claim against a source",
      "title": "Is this supported by that? Answered in milliseconds",
      "summary": "Pass a claim and the passage it should come from. Arbitrel says whether the passage supports it, contradicts it or doesn't say — before the answer reaches a user.",
      "points": [
        "Three-way verdicts: supported, contradicted, not stated",
        "Source passages up to 32k tokens",
        "Cheap enough to run on every generated answer"
      ],
      "example": {
        "endpoint": "POST /v1/decide",
        "request": "{\n  \"model\": \"arbitrel-d2\",\n  \"input\": {\n    \"claim\": \"Refunds take 3 days.\",\n    \"source\": \"Refunds are issued within 5–7 working days.\"\n  },\n  \"decide\": {\n    \"type\": \"choice\",\n    \"options\": [\"supported\", \"contradicted\", \"not_stated\"]\n  }\n}",
        "decision": {
          "type": "choice · 3",
          "value": "contradicted"
        },
        "confidence": 0.95,
        "distribution": [
          {
            "label": "contradicted",
            "p": 0.95
          },
          {
            "label": "not_stated",
            "p": 0.04
          },
          {
            "label": "supported",
            "p": 0.01
          }
        ],
        "latency": "112 ms",
        "tokens": "57 tokens",
        "labels": {
          "request": "Request",
          "response": "Decision",
          "decision": "Value",
          "confidence": "Confidence",
          "latency": "Latency",
          "tokens": "Input tokens"
        }
      }
    }
  ],
  "labels": {
    "cases": "Use cases"
  },
  "action": {
    "label": "See every decision type",
    "href": "#",
    "variant": "secondary"
  }
}